
When an enterprise application crashes, a service stops, or a device falls out of compliance, the default response has historically been a help desk ticket and a human technician. In fleets of thousands of devices, that default response breaks down: tickets pile up, MTTR climbs, and small issues become outages.
Self-healing endpoints reverse that default. Instead of waiting for someone to notice and act, the endpoint detects the issue, decides on a remedy, executes it, and verifies the result — often before the user realises anything happened.
This guide explains what self-healing endpoints are, how they work, what they can and cannot fix, and how to evaluate self-healing capabilities in modern endpoint management platforms. It is part of the broader autonomous endpoint management topic and connects directly to the AEM maturity model — self-healing is what Stage 5 looks like in practice.
What Are Self-Healing Endpoints?
A self-healing endpoint is a device that can automatically detect, diagnose, and remediate common operational issues without requiring IT intervention. The remediation is typically driven by a combination of:
- Predefined policies — e.g., "if service X stops, restart it"
- AI-assisted decision-making — e.g., "this storage pattern indicates imminent failure — clear cache now"
- Closed-loop workflows — confirm the fix worked and escalate only if it didn't
Self-healing is a capability of mature endpoint management platforms, not a standalone product. It sits at the intersection of automation, analytics, and policy-driven remediation. It is also a key building block of autonomous endpoint management, but it can deliver value independently of a full AEM rollout.
How Self-Healing Works
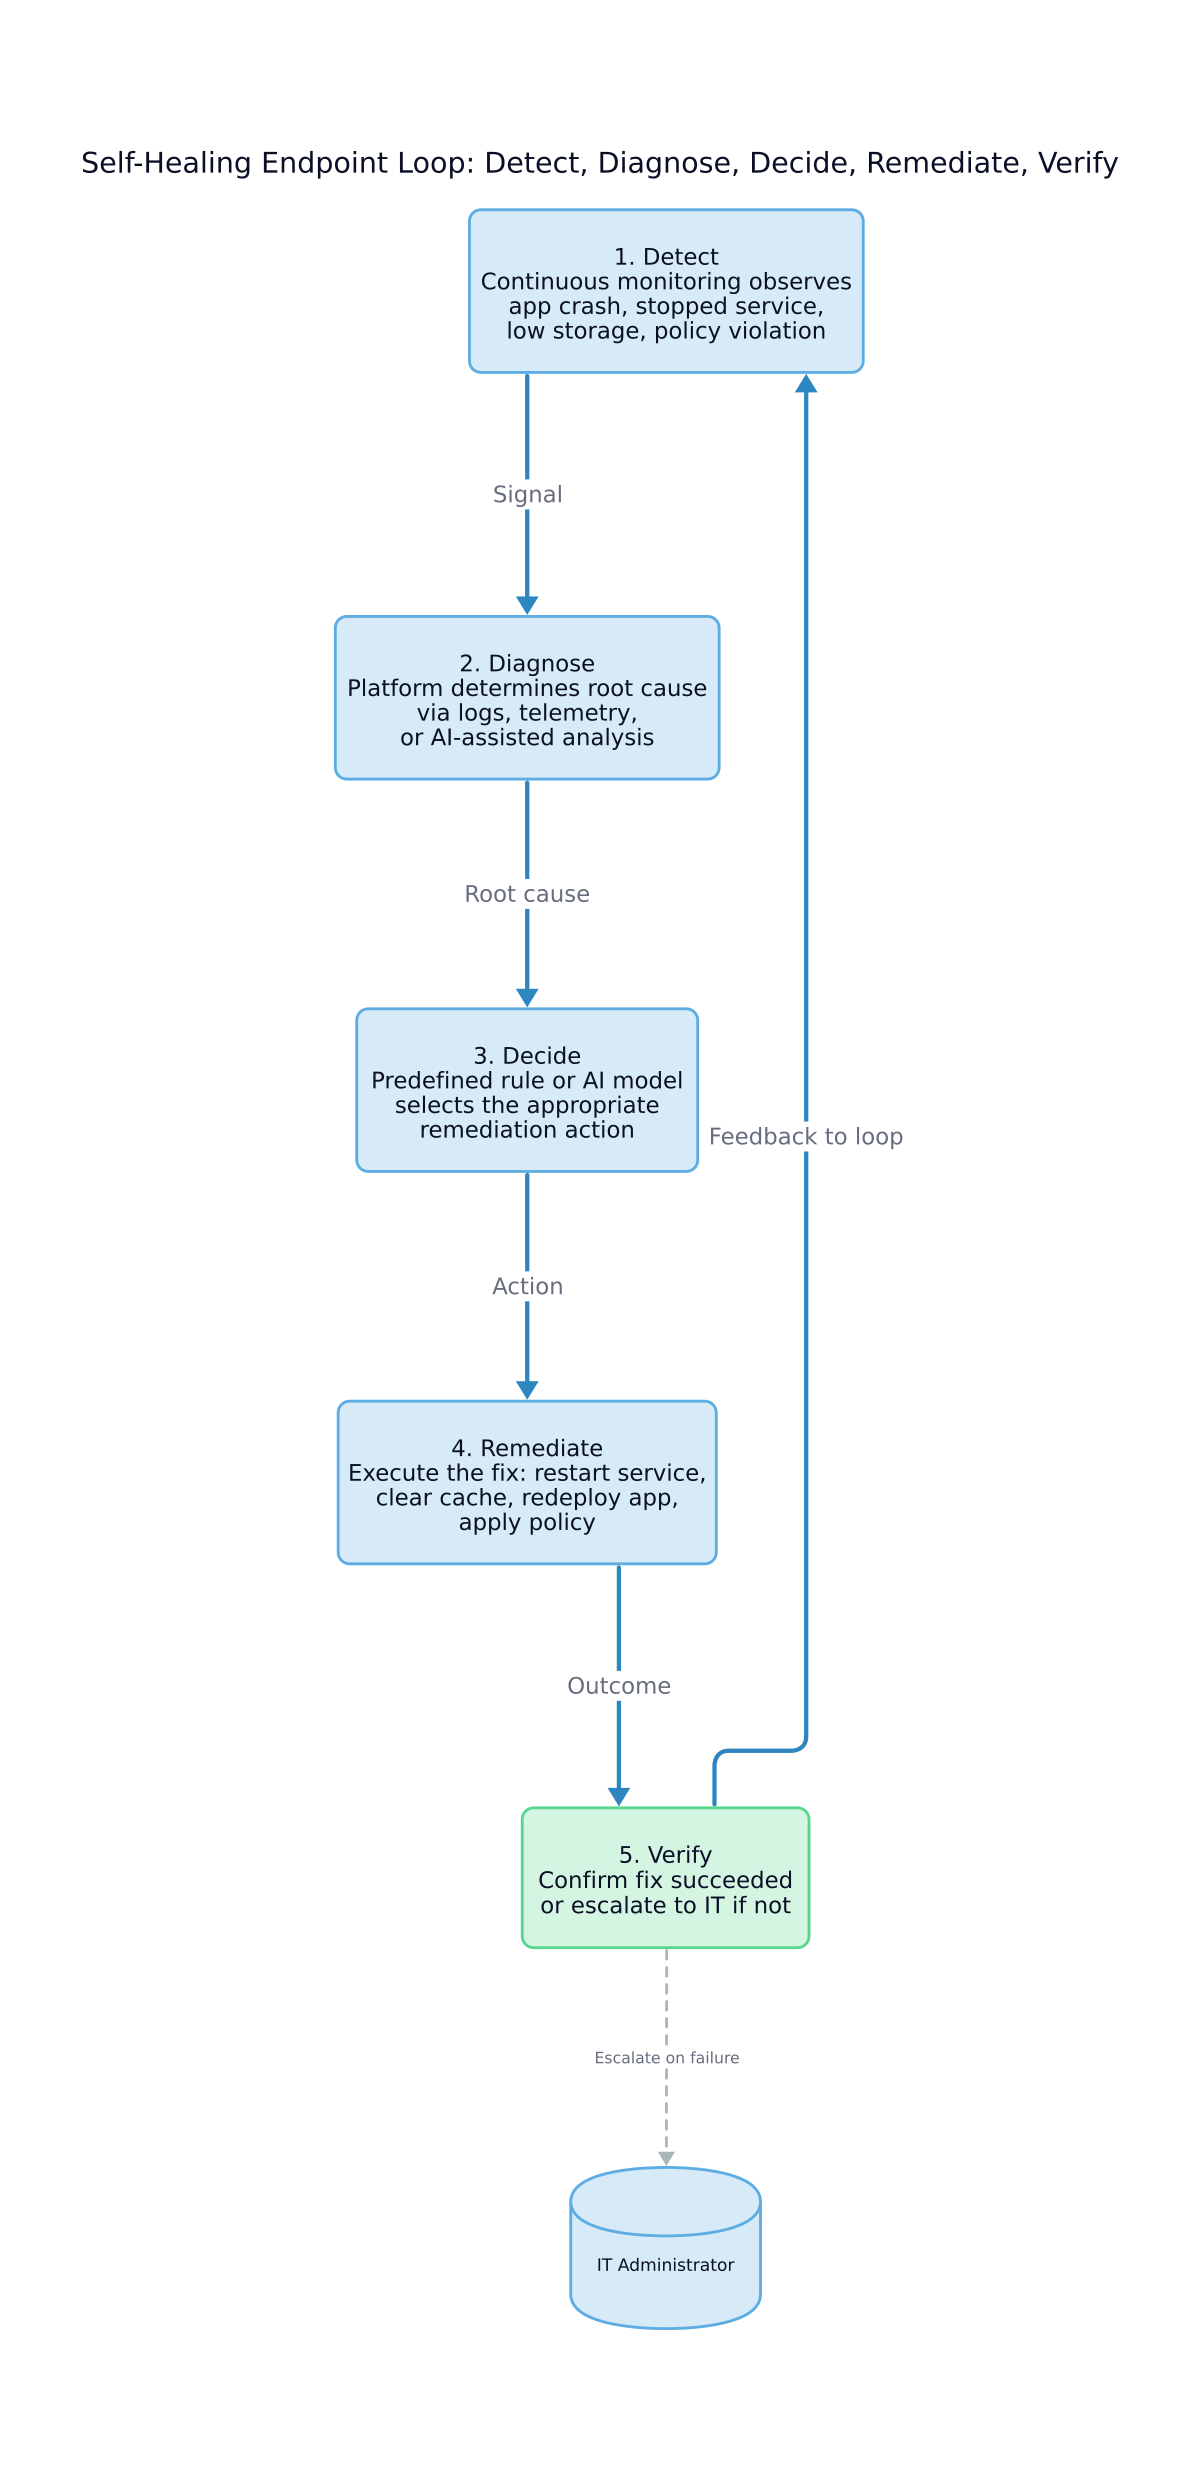
Self-healing follows a continuous loop:
1. Detect. The endpoint or management plane observes a failure condition (app crash, stopped service, low storage, policy violation).
2. Diagnose. The platform determines the root cause using logs, telemetry, or AI-assisted analysis.
3. Decide. A predefined rule or AI model selects the appropriate remediation.
4. Remediate. The platform executes the fix: restart the service, clear cache, redeploy the app, apply a policy.
5. Verify. The platform confirms the issue is resolved; if not, it escalates to IT.
This loop runs continuously across every managed device. The user experiences an interruption — or, more often, doesn't notice anything at all.
What Self-Healing Can Fix
Self-healing is most valuable for high-volume, low-complexity issues. Examples include:
Application issues
- Restarting crashed apps
- Clearing app cache
- Redeploying business-critical apps after corruption
- Re-authenticating expired tokens or certificates
System and service issues
- Restarting stopped OS services
- Reapplying policies after drift
- Re-enabling disabled features (e.g., VPN, encryption)
- Recovering from failed OS updates
Compliance and security issues
- Re-enforcing password policies
- Re-applying kiosk or lockdown profiles
- Quarantining devices that fall out of compliance
- Triggering selective wipe on compromised devices
Performance issues
- Cleaning up disk space before storage exhaustion
- Killing runaway processes
- Rotating logs that have grown too large
A useful framing: anything a Level 1 help desk technician would resolve with a script or a remote session is a candidate for self-healing.
Self-Healing vs Traditional Troubleshooting
| Dimension | Traditional IT | Self-Healing Endpoints |
| Issue detection | User reports, manual checks | Continuous monitoring |
| Diagnosis | Human investigation | Automated root-cause analysis |
| Resolution time | Hours to days | Seconds to minutes |
| Scalability | Linear with headcount | Constant regardless of fleet size |
| User impact | Disruption visible | Often invisible |
| IT effort | High for routine issues | Reserved for exceptions |
The table makes the operational case, but the strategic case is more important. Self-healing is the visible proof that an automation-first endpoint strategy is working. Without self-healing, automation is theoretical. With it, automation is delivering measurable value to users.
Self-Healing in Real Scenarios
Scenario 1 — Field worker handheld scanner stops responding.
A warehouse scanner app crashes mid-shift. Without self-healing, the worker radios for help, an IT ticket is opened, and a technician connects remotely — meanwhile the worker is idle. With self-healing, the management plane detects the crash within seconds, restarts the app, verifies it loaded successfully, and only escalates if the restart fails. For rugged-device scenarios, see MCP-driven self-healing workflows.
Scenario 2 — Compliance drift on a remote laptop.
A user disables the corporate VPN to test a personal app. The endpoint detects the configuration drift, re-applies the security profile, and logs the event. No ticket needed.
Scenario 3 — Storage exhaustion on a kiosk.
A customer-facing kiosk fills its storage with logs over a long weekend. Without self-healing, the device fails open on Monday morning. With self-healing, log rotation runs automatically before storage hits the warning threshold.
Scenario 4 — Self-healing in a macOS fleet.
A macOS management agent monitors for common failure patterns and triggers Python scripts to remediate without user interruption. Read the technical deep-dive in our macOS DDM + Python self-healing guide for a concrete implementation.
What to Look for in Self-Healing Endpoint Software
Not all self-healing is created equal. When evaluating platforms, look for:
- Closed-loop remediation. Can the platform verify that its fix worked and escalate if not?
- Conditional execution. Does remediation run only when triggered by specific events, or blindly on a schedule?
- Safety controls. Can IT set guardrails (e.g., "only restart this service between 9am and 5pm")?
- Audit trail. Every self-healing action should be logged with the trigger, the decision, the outcome, and the verifier.
- Granular policy scope. Can rules target specific device groups, OS versions, or user roles?
- AI-assisted reasoning. Does the platform use AI to diagnose, or only to execute predefined scripts?
- Integration with UEM. Is self-healing native to your endpoint management platform, or a bolted-on tool?
- On-device intelligence. Can the endpoint itself detect and resolve local issues without round-tripping to the cloud? See edge AI for device management for the architectural rationale.
Common Pitfalls
- Over-automation. Remediating too aggressively can mask underlying issues. Always have an escalation path and a human-in-the-loop for high-risk actions.
- False positives. Poorly tuned anomaly detection triggers self-healing on issues that don't exist. AI-assisted diagnosis reduces this but does not eliminate it — review audit logs regularly.
- Blind remediation. Running self-healing without clear policies invites regulatory and security problems. Tie every remediation to a defined policy with explicit boundaries.
- Tool fragmentation. If self-healing lives in a separate product from UEM, the result is gaps. Self-healing should be native to your endpoint management platform.
Where Self-Healing Fits in the AEM Maturity Model
Self-healing is the operational expression of Stage 5 (Autonomous Operations) in the AEM maturity model. It cannot be deployed successfully without the prerequisites of Stages 2–4: mature automation, continuous monitoring, predictive analytics, and governance. Trying to deploy self-healing on top of Stage 1 operations creates the "automation chaos" failure mode described in the maturity guide.
For organisations just beginning the journey, the practical starting point is endpoint automation as the foundation. For those further along, predictive device health is the natural precursor to self-healing — it surfaces the anomalies that trigger remediation.
Conclusion
Self-healing endpoints are the most tangible demonstration that endpoint automation is working. When users stop noticing their devices, when tickets for routine issues drop, and when IT shifts from firefighting to strategy, self-healing has done its job.
For a deeper look at where self-healing fits in the broader journey, see the AEM maturity model. For an implementation reference, see the autonomous endpoint management solution overview and the macOS DDM self-healing deep-dive.