
---
Most endpoint issues do not arrive without warning. Devices that are about to fail typically show signal patterns hours or days in advance — declining battery health, growing storage consumption, repeated app crashes, rising CPU temperature. The challenge is that these signals are buried in dashboards that no one has time to read.
Predictive device health and endpoint anomaly detection change that. Instead of waiting for a help desk ticket, IT teams are notified — or acted upon automatically — when signals cross thresholds that historically have preceded failures. This is the foundation of autonomous endpoint management and a key stage in the AEM maturity model.
This guide explains how predictive analytics works for endpoint fleets, which signals matter most, and how to operationalise it with SureInsights and related capabilities.
From Reactive to Predictive Operations
Traditional endpoint monitoring is reactive. A user reports an issue, the ticket reaches IT, an administrator investigates, and a fix is dispatched. The time between issue and resolution is MTTR.
Predictive operations invert the flow. Instead of reacting to user-reported issues, the platform anticipates them. The metric that matters is no longer MTTR alone — it is time-to-detect and issues prevented before user impact. The shift requires three things: continuous telemetry, intelligent analysis, and workflows that act on the predictions.
This is also the natural precursor to self-healing endpoints — you cannot automate remediation of issues you cannot detect.
Signals to Monitor
Predictive device health is built on telemetry. The most useful signals for endpoint fleets fall into five categories:
Battery and power. Battery health percentage, charge cycle counts, time-to-full-charge trends. A battery that is suddenly losing capacity faster than its age predicts is a likely replacement candidate. A handheld scanner that fails to hold charge mid-shift is a frontline productivity issue.
Storage. Free space trends, growth rate, large-file identification, cache accumulation. Storage exhaustion is one of the most predictable failure modes — it almost always shows warning signs in the days before it happens.
Performance. CPU temperature, memory pressure, app launch times, crash counts. Performance degradation often precedes outright failure by hours or days, especially on long-deployed devices.
Application and service stability. Crash frequency, restart counts, error log volume. An app that crashes repeatedly across a small device cluster may indicate a bad update, a configuration regression, or a compatibility issue.
Compliance and security posture. Encryption status, OS patch level, jailbreak/root indicators, configuration drift. These signals often indicate both operational and security risk and are the natural input to self-healing workflows.
SureInsights, the analytics layer of 42Gears autonomous endpoint management, surfaces these signals across Android, Windows, iOS, macOS, Linux, and ChromeOS fleets from a single dashboard.
How Predictive Analytics Works
Three approaches are common in endpoint management — and the most effective platforms combine them. The maturity progression is:
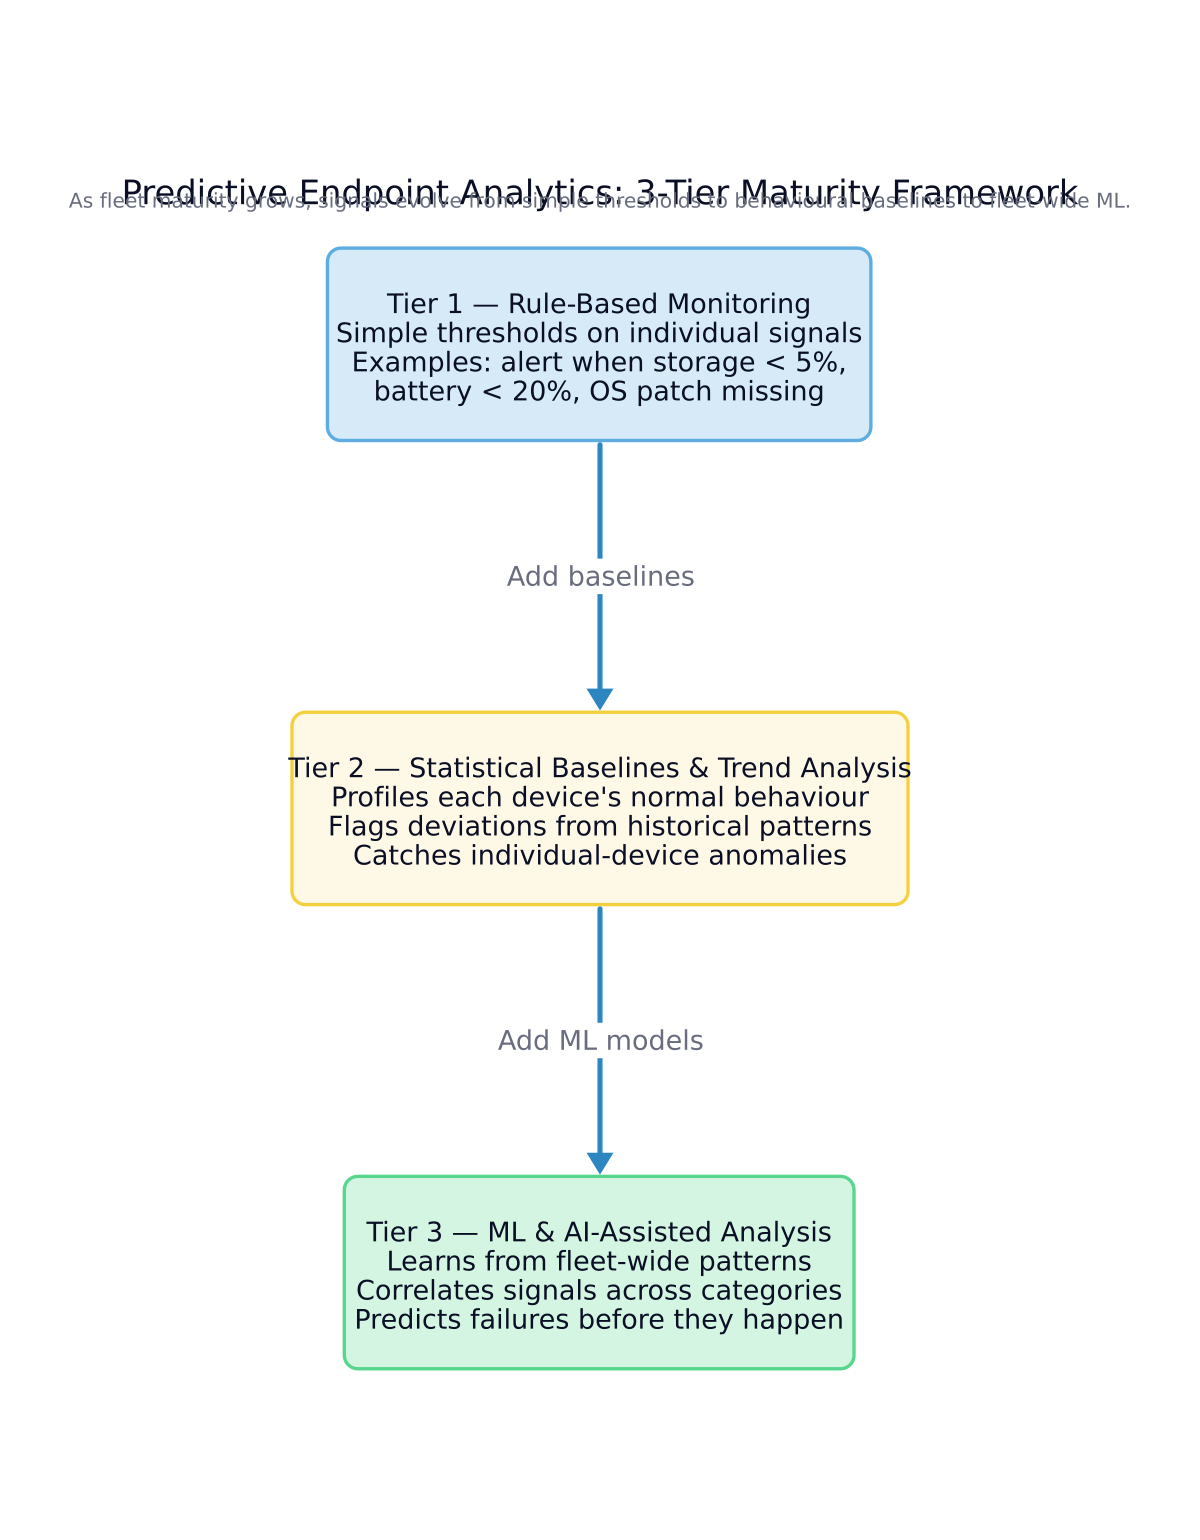
Rule-based monitoring
The simplest form: thresholds on individual signals (e.g., "alert when storage < 5%"). Useful for clear-cut conditions, but brittle for complex patterns. A device that uses 80% storage consistently is not at risk; one that is climbing from 50% to 80% in 48 hours is.
Statistical baselines and trend analysis
Profiles each device's "normal" behaviour and flags deviations. A laptop that has never used more than 40% storage suddenly sitting at 75% is anomalous even if no threshold has been crossed. Statistical approaches catch more issues but generate more false positives.
Machine learning and AI-assisted analysis
Learns from fleet-wide patterns to predict failures before they happen. Can correlate signals across categories (e.g., "rising temperature + declining battery health + increasing crash count = likely imminent failure"). Most effective when trained on labelled failure data, but increasingly useful out-of-the-box with pre-built models.
In production, the most reliable predictive systems combine all three: rules for clear-cut conditions, statistical analysis for individual-device anomalies, and ML models for fleet-wide pattern detection.
Anomaly Detection Approaches
Anomaly detection is the technique that surfaces "this device is doing something unusual." Three families of approach:
- Threshold anomalies — a value crosses a static limit (battery < 20%, storage < 5%).
- Contextual anomalies — a value is unusual given the context (CPU at 95% during a scheduled backup is fine; CPU at 95% at 3am is suspicious).
- Collective anomalies — a pattern across multiple devices signals a fleet-wide issue (10% of Android devices in a region fail to check in within an hour — possible network outage or platform issue).
Effective endpoint platforms combine all three. For architectural context, see our piece on edge AI for device management — on-device anomaly detection reduces cloud round-trips and surfaces local issues faster.
Predictive Health with SureInsights
SureInsights is the analytics layer of the 42Gears autonomous endpoint management solution. It collects telemetry across the managed fleet and surfaces predictive signals in dashboards designed for IT operations:
- Device health dashboards that highlight declining battery health, storage pressure, and connectivity issues before they become tickets.
- Application usage analytics that identify which apps are actually used, which crash frequently, and which silently fail in the background.
- Compliance drift detection that surfaces devices falling out of policy in real time, with automated remediation paths via SureFlow Studio.
- AI-assisted querying through DeepThought 2.0, letting administrators ask natural-language questions like "Which devices in the warehouse fleet are likely to fail in the next 30 days?"
SureInsights works across all supported operating systems and device types — Android, Windows, iOS/iPadOS, macOS, Linux, ChromeOS, Wear OS, VR, and specialised enterprise devices.
From Anomaly Detection to Action
Predictive signals are only valuable if they lead to action. Three patterns are common:
Notify. Surface the prediction to administrators via dashboards, email, or ITSM integration. Works for low-volume, high-stakes issues.
Automate. Trigger a remediation workflow directly. Best for high-confidence, low-risk actions — e.g., "clear cache when storage < 10%". See our piece on self-healing endpoints for what good remediation looks like.
Escalate. When a prediction indicates a high-stakes issue (security compromise, imminent data loss), escalate to a human or to a tier-2 workflow. Predictions without escalation paths become noise.
The maturity progression is from notify to automate, with escalate reserved for the highest-stakes cases. Most organisations begin with notify and progressively automate as confidence in the predictions grows.
Building a Predictive Health Program
Practical steps to operationalise predictive device health:
1. Establish telemetry baseline. Before predicting anything, ensure continuous telemetry is in place for the signals you care about. Endpoint automation is the prerequisite.
2. Start with rules, then add intelligence. Threshold-based alerts are the easiest starting point. Layer statistical and ML-based detection once the rule-based system is stable.
3. Measure prediction accuracy. Track every prediction: was the issue real, was it remediated in time, was it a false positive? Use this to tune models and to build trust with administrators.
4. Connect predictions to workflows. A prediction without an action is just a dashboard. Tie each high-value prediction to a remediation workflow or escalation path.
5. Iterate. Predictive systems improve with usage. Review false-positive rates quarterly, add new signal categories as the fleet evolves, and retire predictions that consistently fail.
Where Predictive Health Fits in the AEM Maturity Model
Predictive operations is Stage 4 in the AEM maturity model. It is the bridge between mature automation (Stage 3) and autonomous operations (Stage 5). Without predictive signals, self-healing cannot know what to heal. Without self-healing, predictive signals become noise.
For organisations earlier in the maturity curve, the endpoint automation foundation guide describes the prerequisite work. For those ready to advance, SureInsights and DeepThought 2.0 provide the analytics and AI layers that turn telemetry into action.
Conclusion
Predictive device health and endpoint anomaly detection are the operational backbone of autonomous endpoint management. They move IT from reactive ticket handling to proactive issue prevention, and they provide the signals that make self-healing endpoints possible.
For a deeper look at how predictive operations fit in the broader journey, see the AEM maturity model. For an implementation reference, see the autonomous endpoint management solution overview and the SureMDM product page.